Seedance 2.5: 30 seconds in one generation
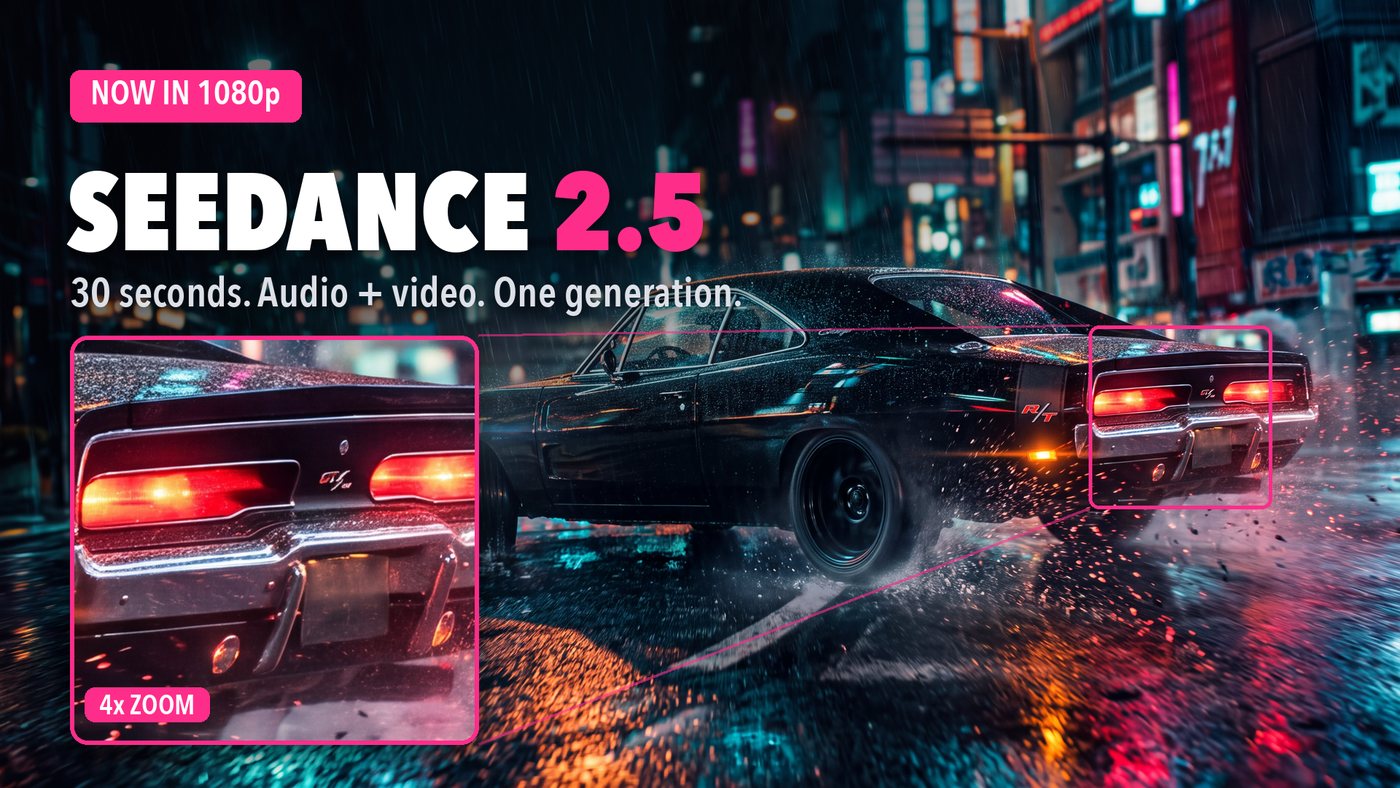
ByteDance's new audio-video model, now on Covely. Picture and sound are generated together in a single pass, motion is smoother and more consistent, and one generation now runs a full 30 seconds.
Seedance 2.5
→ 30 seconds in one take
One generation, up to 30 seconds, and you can extend it twice when the story needs more. Full scenes instead of clips you have to stitch together.
→ And now at 1080p
The full thirty seconds render in 1080p, so what comes out of the generation is what you publish.
→ Audio and video, generated together
It's a joint audio-video model: the sound comes out of the same generation as the picture, instead of being added on top afterwards.
→ It reads your reference, not just the movement
Feed it a reference video and it picks up framing and cinematic language, not only motion. Plus green-screen output and real camera-move control for production work.